Filter:
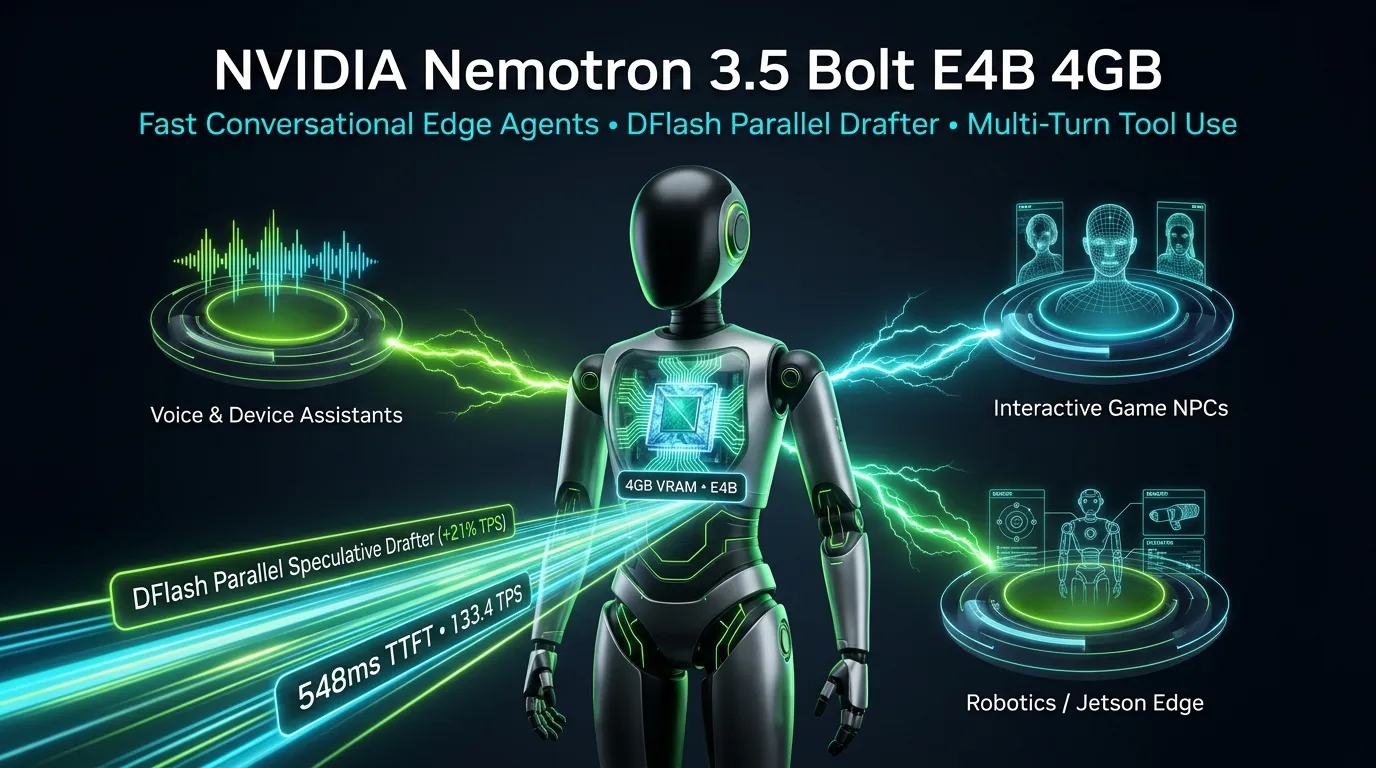
NVIDIA Nemotron 3.5 Bolt E4B 4GB: Fast Conversational Edge Agents, Pure RL Post-Training, and DFlash Parallel Speculative Decoding
Oct 24, 2026

NVIDIA Nemotron 3.5 Bolt E4B 4GB: Fast Conversational Edge Agents, Pure RL Post-Training, and DFlash Parallel Speculative Decoding

Inside NVIDIA's Nemotron 3.5 Bolt E4B 4GB: how pure RLVR/RLHF post-training on Gemma-4-E4B-it, cyclical verbosity control, and a 5-layer DFlash parallel speculative drafter deliver 70.2 benchmark accuracy and 272.6 tokens/sec inside a 4GB VRAM envelope for robotics, game NPCs, and voice assistants.
The Always-On Agent Showdown: Architectural, Security, and Autonomy Comparison Across Meta Muse, OpenAI Dots, Google Gemini Spark, and Perplexity Computer
Oct 9, 2026

The Always-On Agent Showdown: Architectural, Security, and Autonomy Comparison Across Meta Muse, OpenAI Dots, Google Gemini Spark, and Perplexity Computer

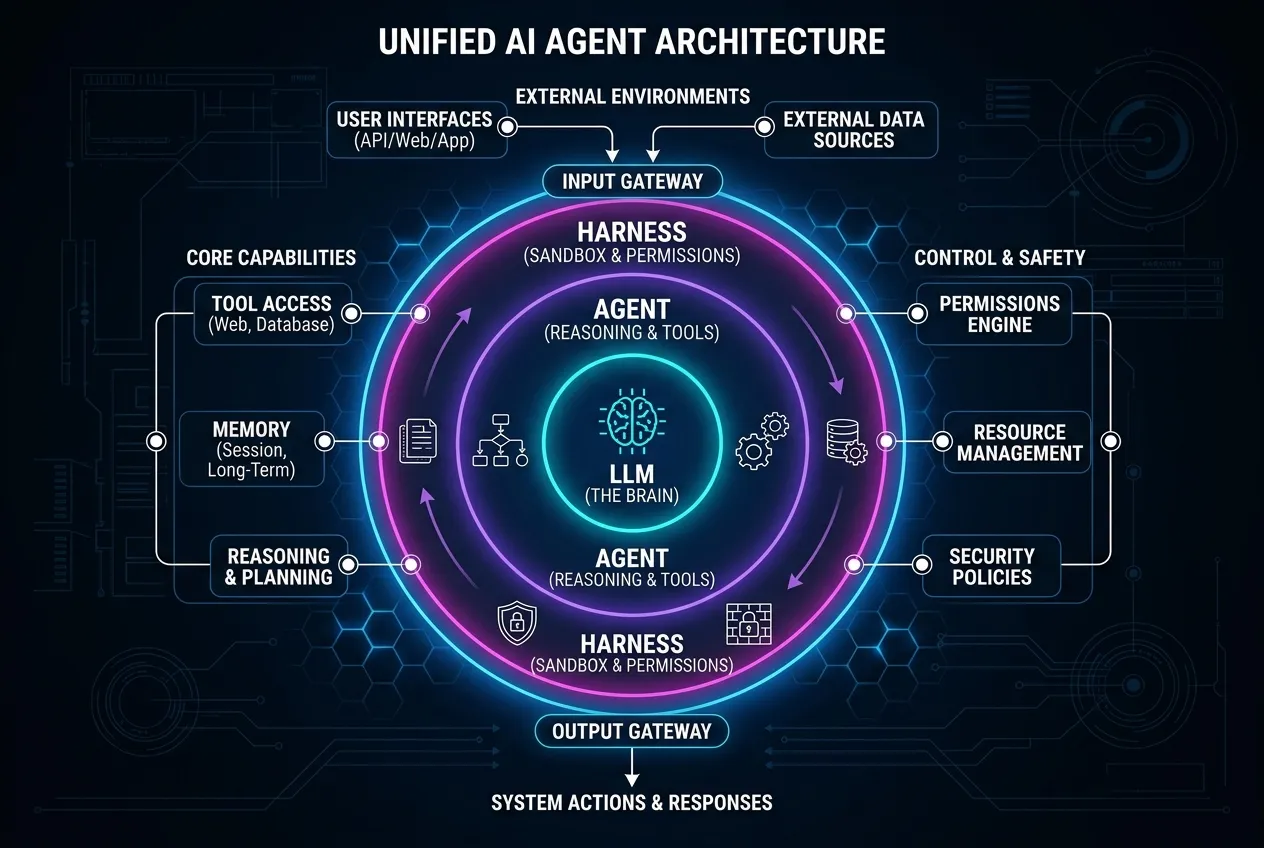
A head-to-head architectural breakdown of the leading 2026 always-on agent frameworks: Meta Muse, OpenAI Dots, Google Gemini Spark, and Perplexity Computer across sandboxes, security, routing, and autonomy.
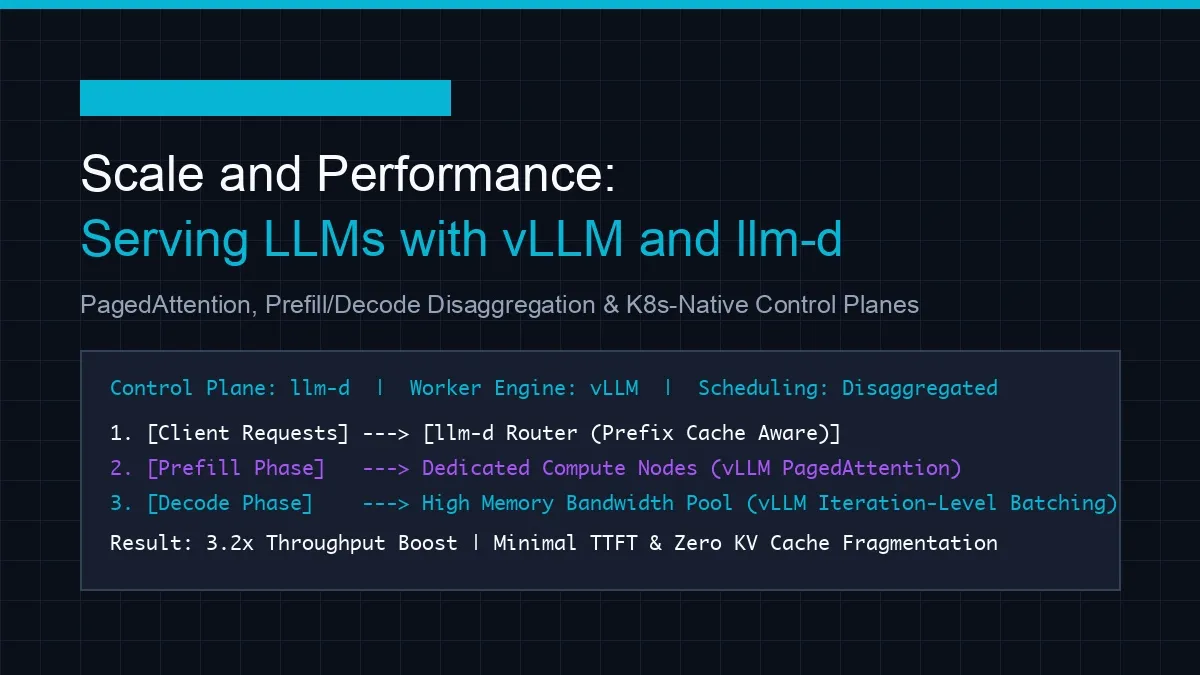
Running Local LLMs: Ollama vs. vLLM
Jul 4, 2026

Running Local LLMs: Ollama vs. vLLM

A comprehensive guide to running Large Language Models locally on Windows, macOS, and Linux using Ollama and vLLM, including pros, cons, and performance tuning.