Qwen4-Max Preview: 1M Multimodal Context, 393K Thinking Budget, and Alibaba's Open-Weights Crossroads
Inside Alibaba's time-limited qwen4-max-preview release: 1M context, 393K shared reasoning output, Token Plan gating, and the Qwen 4 open-source debate.
Summary
On November 11, 2026, Alibaba Cloud quietly opened a two-week developer preview for its next-generation flagship model: Qwen4-Max (qwen4-max-preview / qwen4.0-max-preview). Running strictly through November 25, 2026 (24:00 UTC+8) before the preview snapshot is retired, this release gives engineers their first hands-on look at Alibaba’s fourth-generation flagship—featuring a 1-million-token multimodal context window (text, image, and video), an unusually large 393,216-token shared thinking-and-output budget, configurable reasoning_effort, and native compatibility with both OpenAI and Anthropic Messages APIs.
Yet the bigger story is structural: Qwen 4 (the full four-tier family announced at Apsara) is not out yet, and Qwen4-Max Preview is closed-source and subscription-gated behind Alibaba Cloud Model Studio’s Token Plan. With zero pay-as-you-go token pricing, zero official benchmark tables, and no downloadable weights—despite Alibaba’s track record of open-sourcing 470+ models—this preview highlights a sharp tension between frontier monetization and open-weight community expectations.
Official Model Card & Preview Summary
| Specification | Qwen4-Max Preview Details |
|---|---|
| Model ID / Aliases | qwen4-max-preview, qwen4.0-max-preview |
| Provider & Surface | Alibaba Cloud Model Studio Token Plan, Qwen Chat, Qwen Studio |
| Release Status | Time-Limited Preview (Nov 11, 2026 10:00 UTC+8 → Nov 25, 2026 24:00 UTC+8) |
| Context Window | 1,000,000 tokens (native text, image, and video inputs) |
| Max Output Budget | 393,216 tokens (dynamically shared between internal thinking and final answer) |
| Reasoning Controls | Thinking enabled by default; adjustable reasoning_effort (low, medium, xhigh) |
| API Protocols | OpenAI Chat Completions, OpenAI Responses, Anthropic Messages API, JSON Schema |
| Billing & Access | Subscription-only via Token Plan (Personal / Team tiers; ~$3–$6/mo intro promos) |
| Open Weights / GA | Proprietary preview only; no GA date, pay-as-you-go rate, or Hugging Face weights yet |
Prior Reading Material
To contextualize Qwen4-Max Preview against Alibaba’s previous generation and competing 1M-context frontier models, explore these prerequisite deep dives:
- Frontier MoE Deep-Dive: Analyzing Alibaba’s Qwen 3.8 Flagship Architecture, Performance, and Token Pricing — Architectural baseline for Alibaba’s Qwen 3.8 generation, Mixture-of-Experts routing, and token economics.
- Qwen3.8-Omni-Flash: Native Audio-Visual Reasoning, Agentic Perception, and Sub-Second Tool Use — How Alibaba’s previous-gen multimodal pipeline unified vision, audio, and tool execution.
- Gemini 4 Hydrogen: 2.5x Faster Agentic Execution, 1M Unified Context, and the Antigravity Orchestrator — Google DeepMind’s configurable thinking tiers (
LOW–XHIGH) and 1M unified context budget. - DeepSeek V4.1-Flash-1017: MIT Weights, DeepInfer Engine, Agent Harness Tuning, and the Full-Stack Search/Fetch API Play — Comparing open-weight MIT releases with closed commercial preview endpoints.
1. Qwen 4 vs. Qwen4-Max: Clearing Up the Release Confusion
If you have seen conflicting headlines claiming “Qwen 4 is out” alongside posts saying “Qwen 4 hasn’t launched yet,” both are partially right—because Alibaba separated the family announcement from its first shipped endpoint.
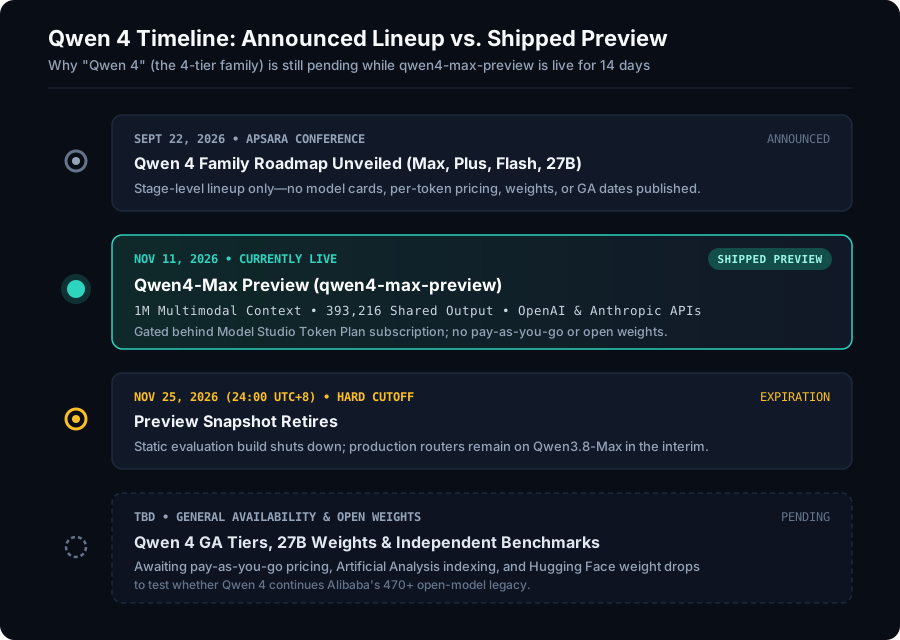 Figure 1: Comparing the full Qwen 4 lineup announced at Apsara (September 22, 2026) against the single time-limited
qwen4-max-preview endpoint shipped on November 11, 2026. Source: Alibaba Cloud documentation and OrcaRouter analysis.
Here is the exact distinction between the two:
- The Qwen 4 Family (Announced, Not Yet Shipped): At the Apsara conference in Hangzhou on September 22, 2026, Alibaba previewed a four-tier Qwen 4 generation: Max (flagship), Plus (balanced), Flash (high-throughput), and 27B (open weights). At that stage, those tiers were roadmap names without public model cards, per-token pricing, or downloadable weights.
- Qwen4-Max Preview (Shipped, Time-Limited): On November 11, 2026, Alibaba shipped a single static evaluation snapshot—
qwen4-max-preview—inside Model Studio’s Token Plan, Qwen Chat, and Qwen Studio. It expires on November 25, 2026, and production routers like OrcaRouter note that live production traffic still defaults to Qwen3.8-Max (see our Qwen 3.8 deep dive) until permanent GA endpoints arrive.
2. Inside qwen4-max-preview: Context, Shared Thinking, and Dual APIs
Despite being a two-week preview, the technical specifications of qwen4-max-preview reveal how Alibaba is positioning its fourth-generation flagship for long-horizon coding and multimodal agentic loops.
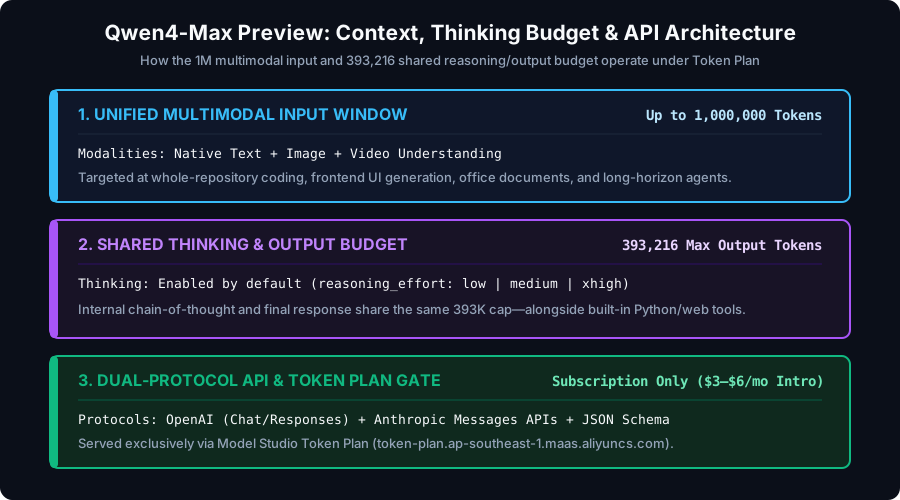 Figure 2: Architectural overview of
qwen4-max-preview—pairing a 1M multimodal input window with a 393,216-token shared thinking/output budget and dual OpenAI/Anthropic protocol support.
1M Multimodal Context & 393,216 Shared Output Tokens
While 1M-token context windows are increasingly table stakes for frontier models, qwen4-max-preview pairs its 1M input window (supporting text, images, and video, building on Qwen3.8-Omni-Flash) with a 393,216-token output ceiling. Crucially, that 393K budget is dynamically shared between internal chain-of-thought reasoning tokens and the final user-visible response—preventing long-running coding or frontend-generation trajectories from truncating mid-thought.
Configurable reasoning_effort & Self-Verifying Tool Loops
Deep reasoning is enabled by default (xhigh as the default tier, alongside low and medium), similar to the tiered thinking controls we examined in Gemini 4 Hydrogen and Claude Fable 5.2. Early developer testing reported by MobiDevices and hands-on evaluators notes two practical behaviors:
- Autonomous Code Verification: When tackling logic or math-heavy tasks, the preview model frequently writes and executes its own Python verification scripts in a tool loop before emitting a final answer.
- Drop-In OpenAI & Anthropic Compatibility: Alibaba exposed
qwen4-max-previewacross OpenAI Chat Completions, OpenAI Responses, and Anthropic Messages API formats with native JSON Object and JSON Schema structured outputs—making it trivial to swap into existing agent harnesses without rewriting SDK clients.
3. The Token Plan Gate & The “470 Models” Open-Source Tension
The most debated aspect of qwen4-max-preview is not its context length—it is how it is distributed.
flowchart TD
    classDef step fill:#0f172a,stroke:#38bdf8,stroke-width:2px,color:#ffffff;
    classDef warn fill:#1c1812,stroke:#f59e0b,stroke-width:2px,color:#ffffff;
    classDef purple fill:#181326,stroke:#a855f7,stroke-width:2px,color:#ffffff;

    A["Legacy Track Record: Alibaba open-sources 470+ Qwen models globally"]:::step
    B["Nov 11 Preview: qwen4-max-preview ships closed-source behind Token Plan"]:::warn
    C["Missing Signals: Zero pay-as-you-go rates, zero official benchmarks, no 27B weights"]:::warn
    D["Community Debate: Fears of a proprietary pivot vs. leadership pledge to keep open weights"]:::purple
A --> B --> C --> D- Subscription-Only Token Plan: Instead of publishing per-million-token API rates (like Meta Muse Ember’s $0.10/M execution pricing), Alibaba gated
qwen4-max-previewexclusively behind Model Studio’s Token Plan (Personal and Team subscriptions, with introductory tiers around $3–$6/month and off-peak quota incentives). - Zero Official Benchmarks or Independent Indexing: Because the model is restricted to a closed, two-week subscription endpoint with no public pay-as-you-go API or open weights, Alibaba has not published official benchmark tables, and independent evaluators such as Artificial Analysis have not yet indexed Qwen 4 scores.
- The Open-Weights Crossroads: As documented in Shattered.io’s analysis, Alibaba executives recently highlighted that the company has open-sourced over 470 Qwen models to date. Shipping Qwen 4’s debut solely as a closed, time-limited cloud preview—without releasing the promised Qwen 4 27B open-weight model alongside it—triggered widespread skepticism across
r/LocalLLaMAand X. Qwen leadership subsequently reiterated that open-weight releases remain part of the Qwen 4 and Qwen 5 roadmap, leaving developers watching closely for whether the GA launch restores full open-weight parity (comparable to DeepSeek’s MIT-licensed releases).
4. Connecting to qwen4-max-preview (Token Plan API)
If you have an active Alibaba Cloud Model Studio Token Plan subscription before the November 25, 2026 retirement date, you can invoke qwen4-max-preview via the OpenAI-compatible SDK pointed at the Token Plan regional endpoint.
Click to expand runnable code script
# File: test_qwen4_max_preview.py
# Execution: python3 test_qwen4_max_preview.py (requires Model Studio Token Plan API key)
# Relevance: Demonstrates OpenAI-compatible invocation of qwen4-max-preview with reasoning_effort

import os
from openai import OpenAI

client = OpenAI(
    api_key=os.getenv("ALIBABA_TOKEN_PLAN_KEY", "your-token-plan-api-key"),
    base_url="https://token-plan.ap-southeast-1.maas.aliyuncs.com/v1",
)

response = client.chat.completions.create(
    model="qwen4-max-preview",
    messages=[
        {
            "role": "system",
            "content": "You are a systems architect analyzing GPU memory bottlenecks.",
        },
        {
            "role": "user",
            "content": "Compare 1M context KV cache pressure under FP8 vs. MLA.",
        },
    ],
    extra_body={"reasoning_effort": "medium"},
)

print(response.choices[0].message.content)
5. What to Watch Next: GA Launch & Open-Weights Verdict
Treat qwen4-max-preview as a time-boxed architectural preview, not a production dependency. Between now and the official General Availability rollout, three concrete signals will determine whether Qwen 4 reshapes the 2026 frontier landscape:
- GA Pricing & Pay-As-You-Go API: Whether Alibaba opens standard per-token billing for
Qwen 4 Max,Plus, andFlashafter the November 25 preview window closes. - Independent Artificial Analysis Benchmarks: Where Qwen 4 Max lands on coding, agentic tool-use, and reasoning leaderboards once evaluators gain unrestricted API access.
- Qwen 4 27B Open Weights: Whether Alibaba follows through on its open-source commitment with downloadable weights and permissive licensing—or keeps its strongest capabilities behind Token Plan subscriptions.